@inproceedings{zhou2026physinone,title={PhysInOne: Visual Physics Learning and Reasoning in One Suite},author={{PhysInOne Team}},booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},pages={33131--33142},year={2026},}
2025
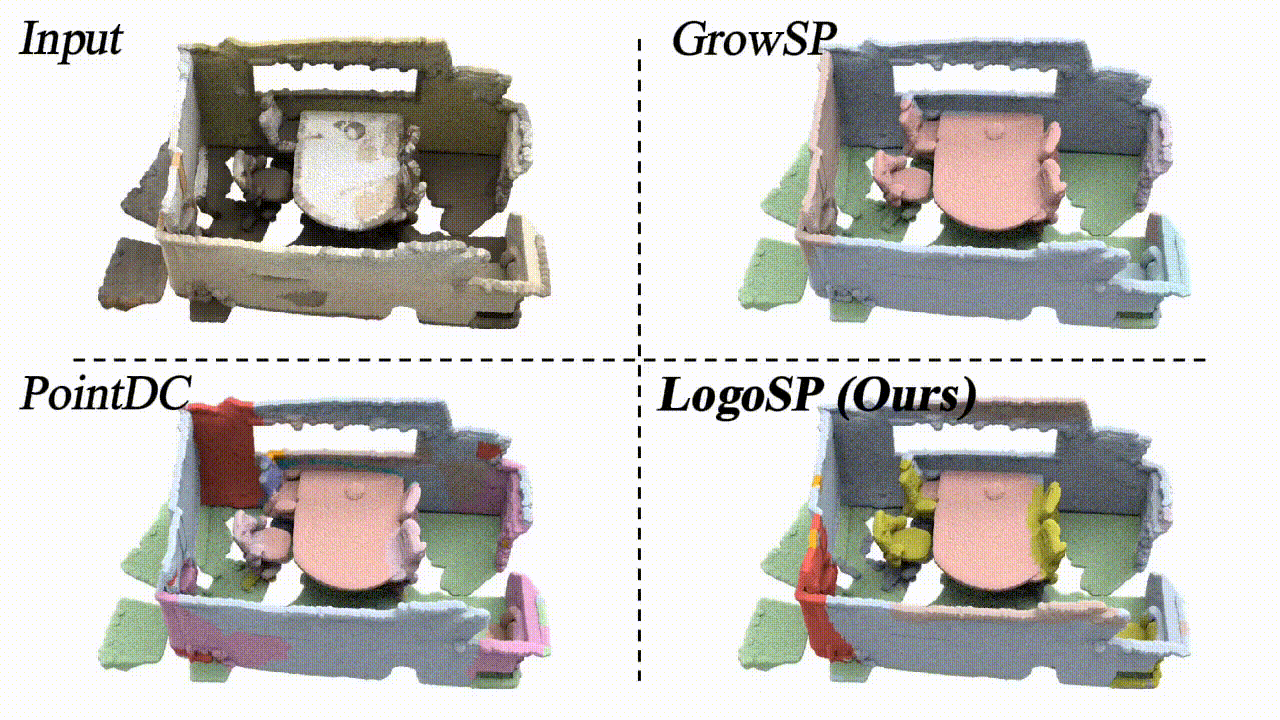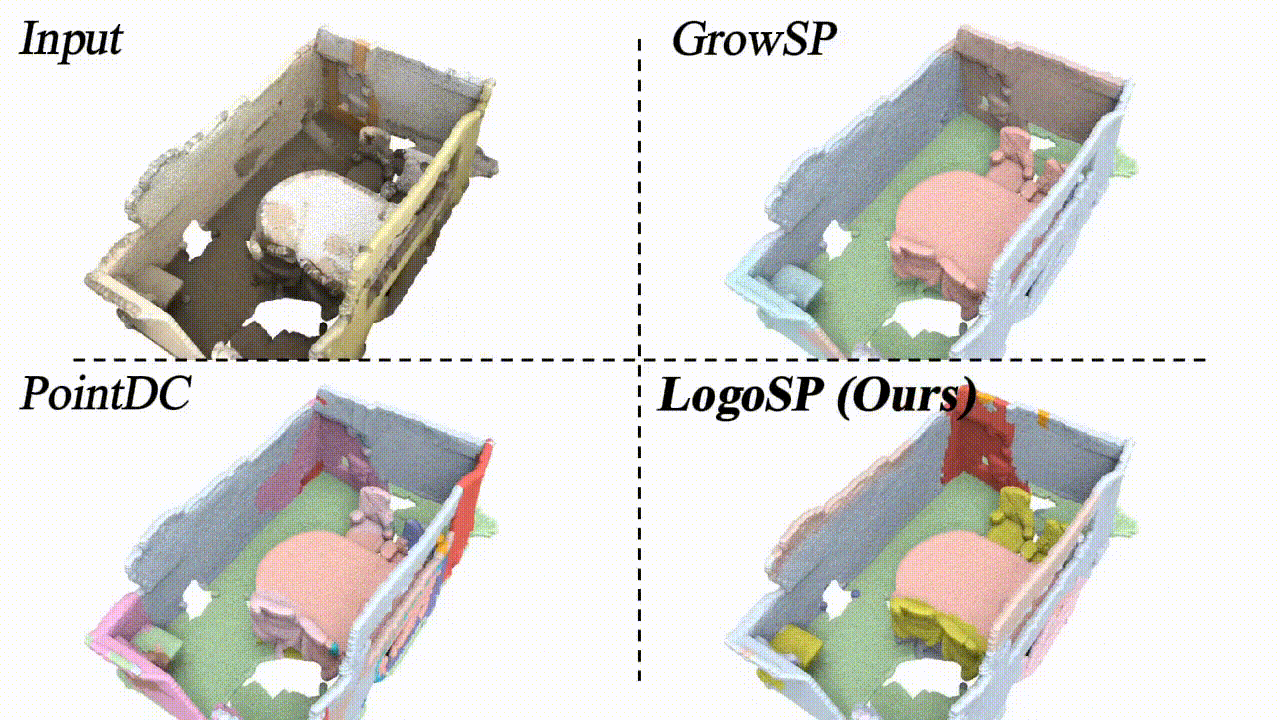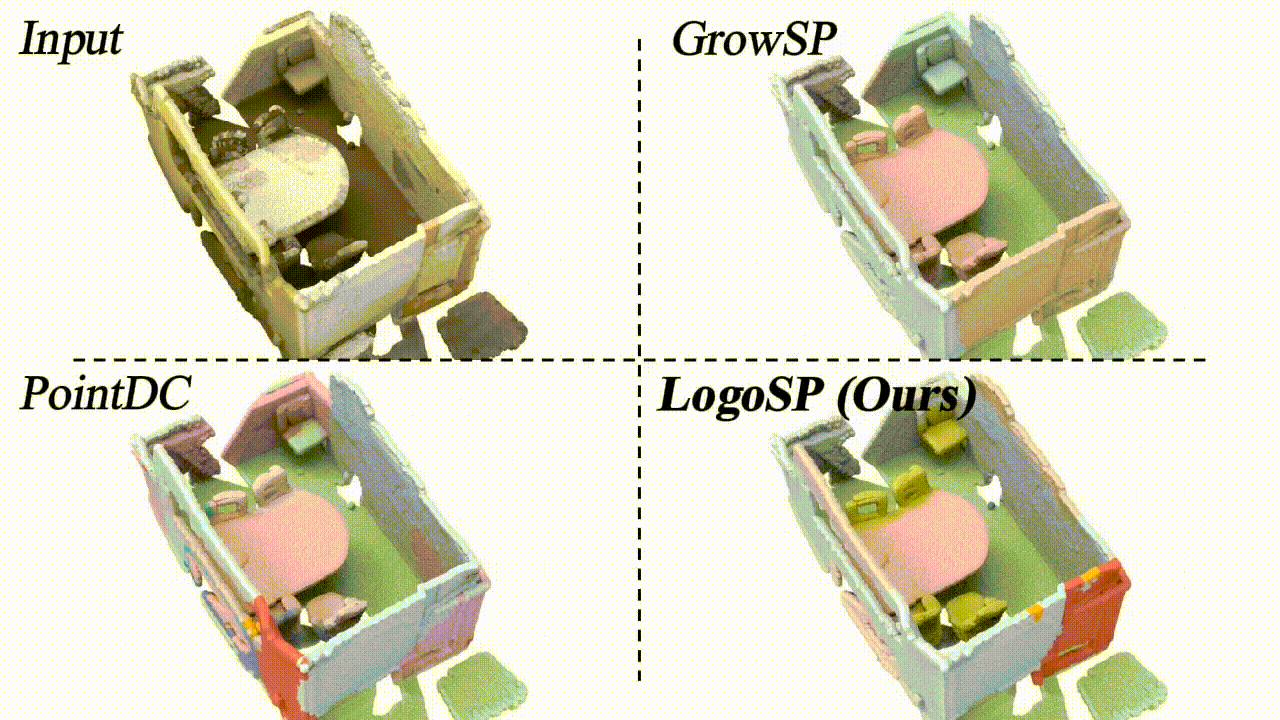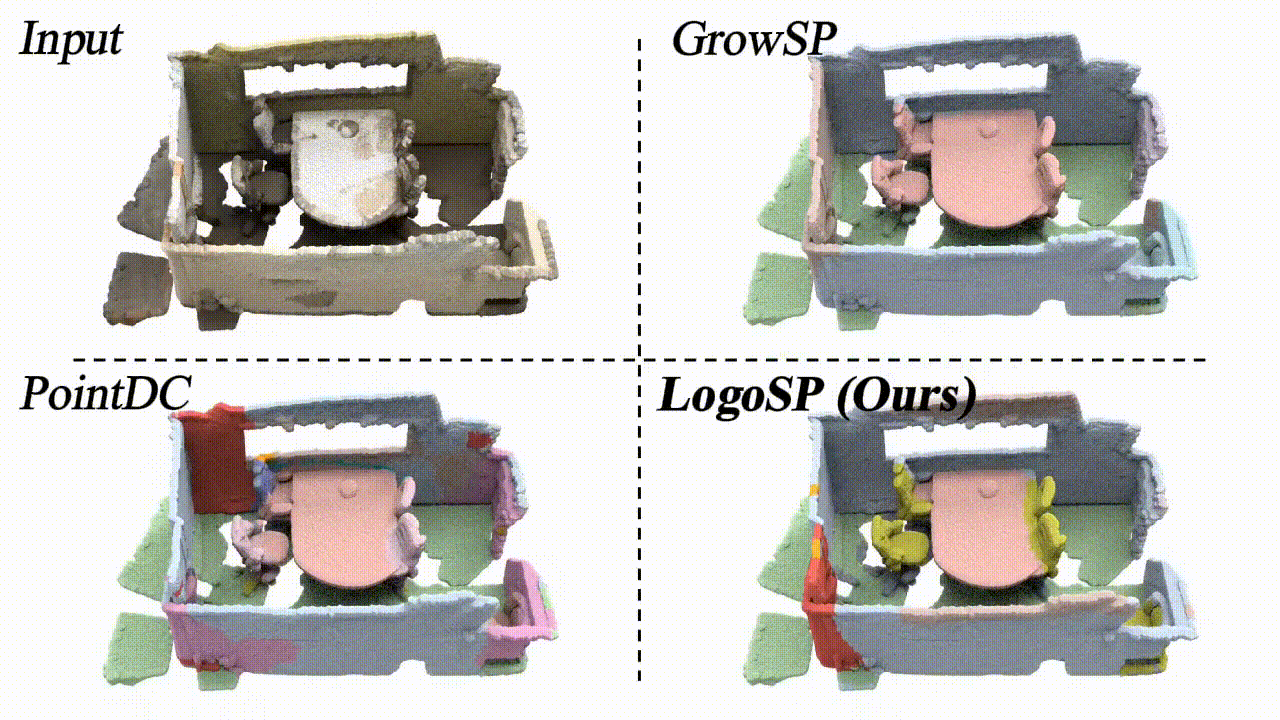
LogoSP: Local-global Grouping of Superpoints for Unsupervised Semantic Segmentation of 3D Point Clouds
@inproceedings{zhang2025logosp,title={{LogoSP}: Local-global Grouping of Superpoints for Unsupervised Semantic Segmentation of 3D Point Clouds},author={Zhang, Zihui and Dai, Weisheng and Wen, Hongtao and Yang, Bo},booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},pages={1374--1384},year={2025},}
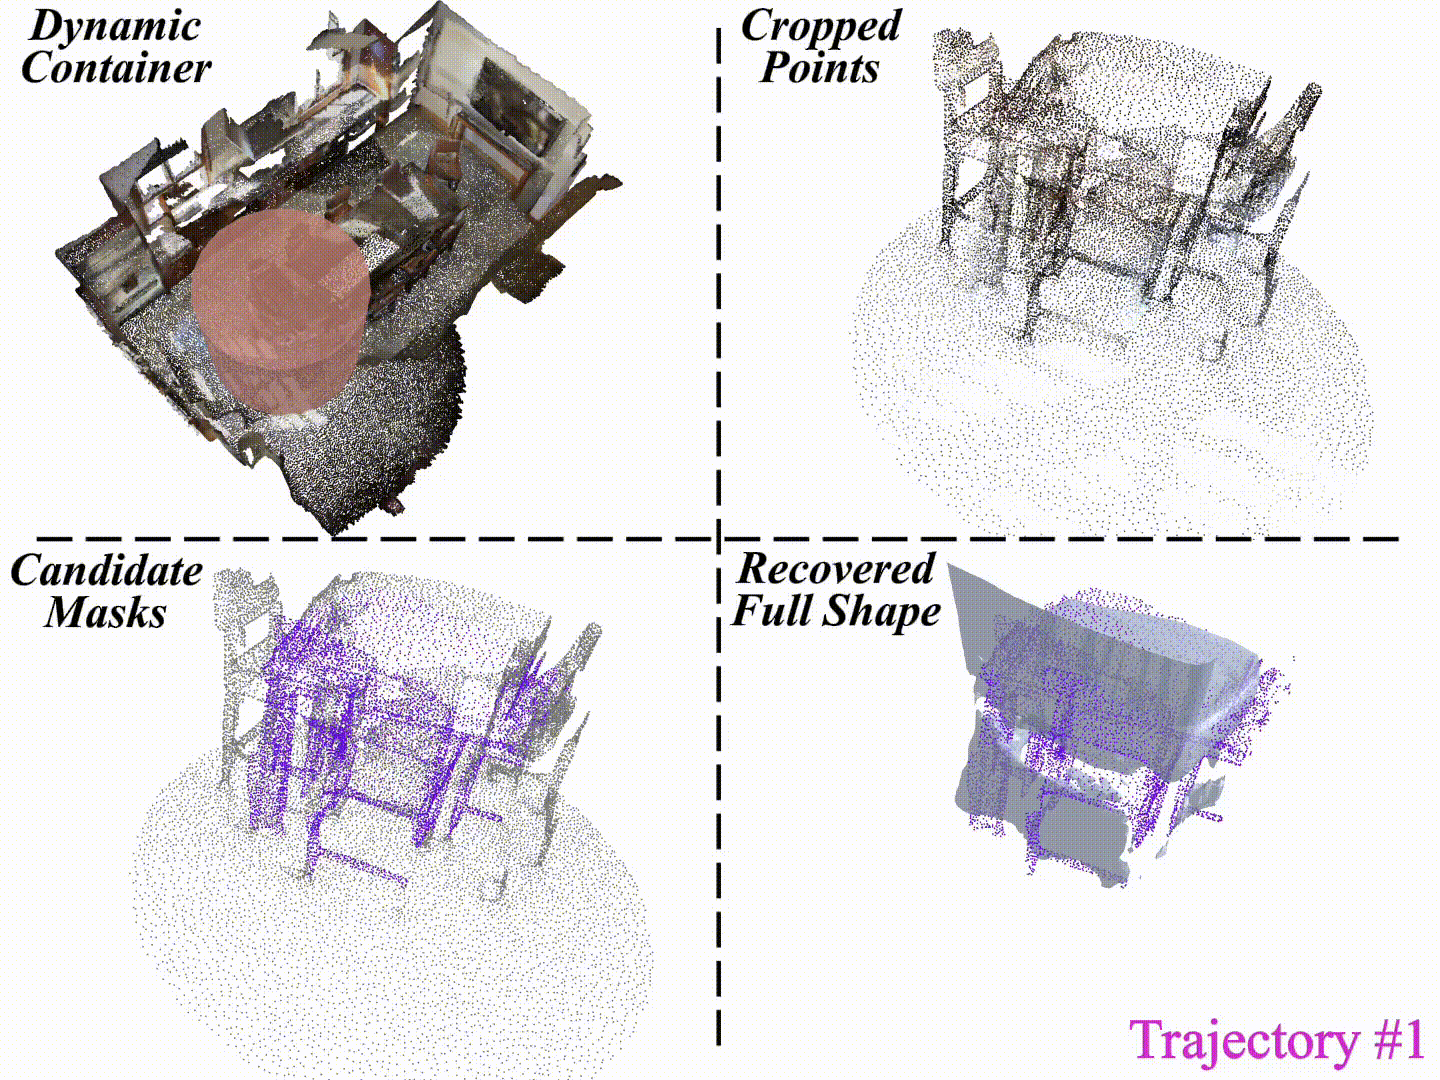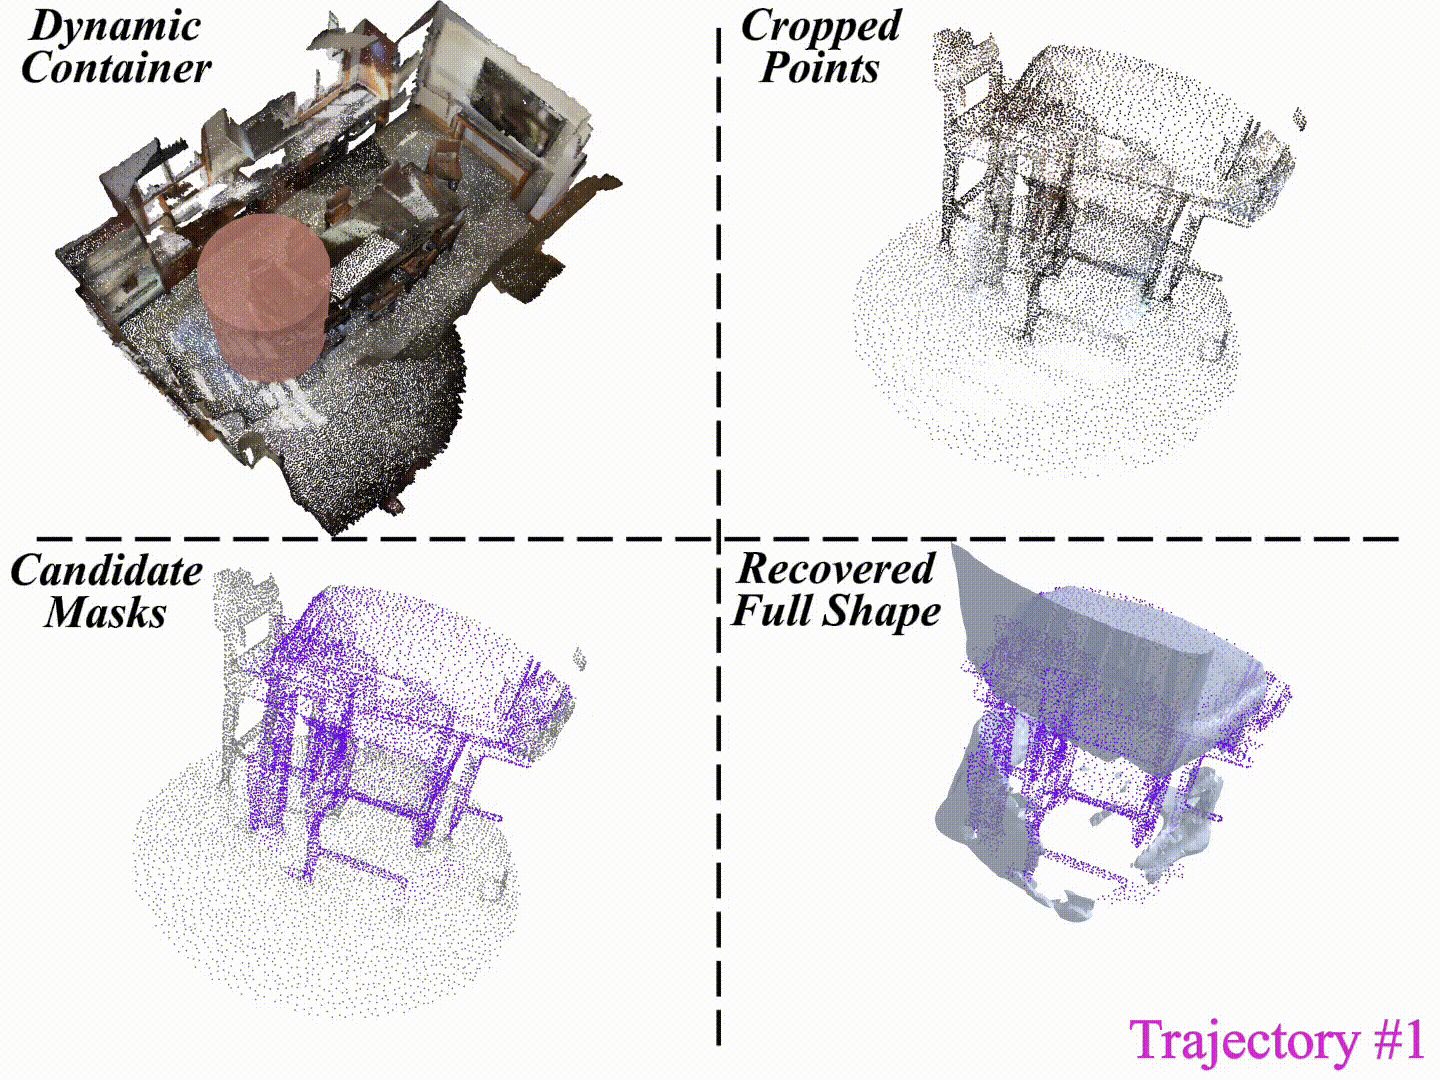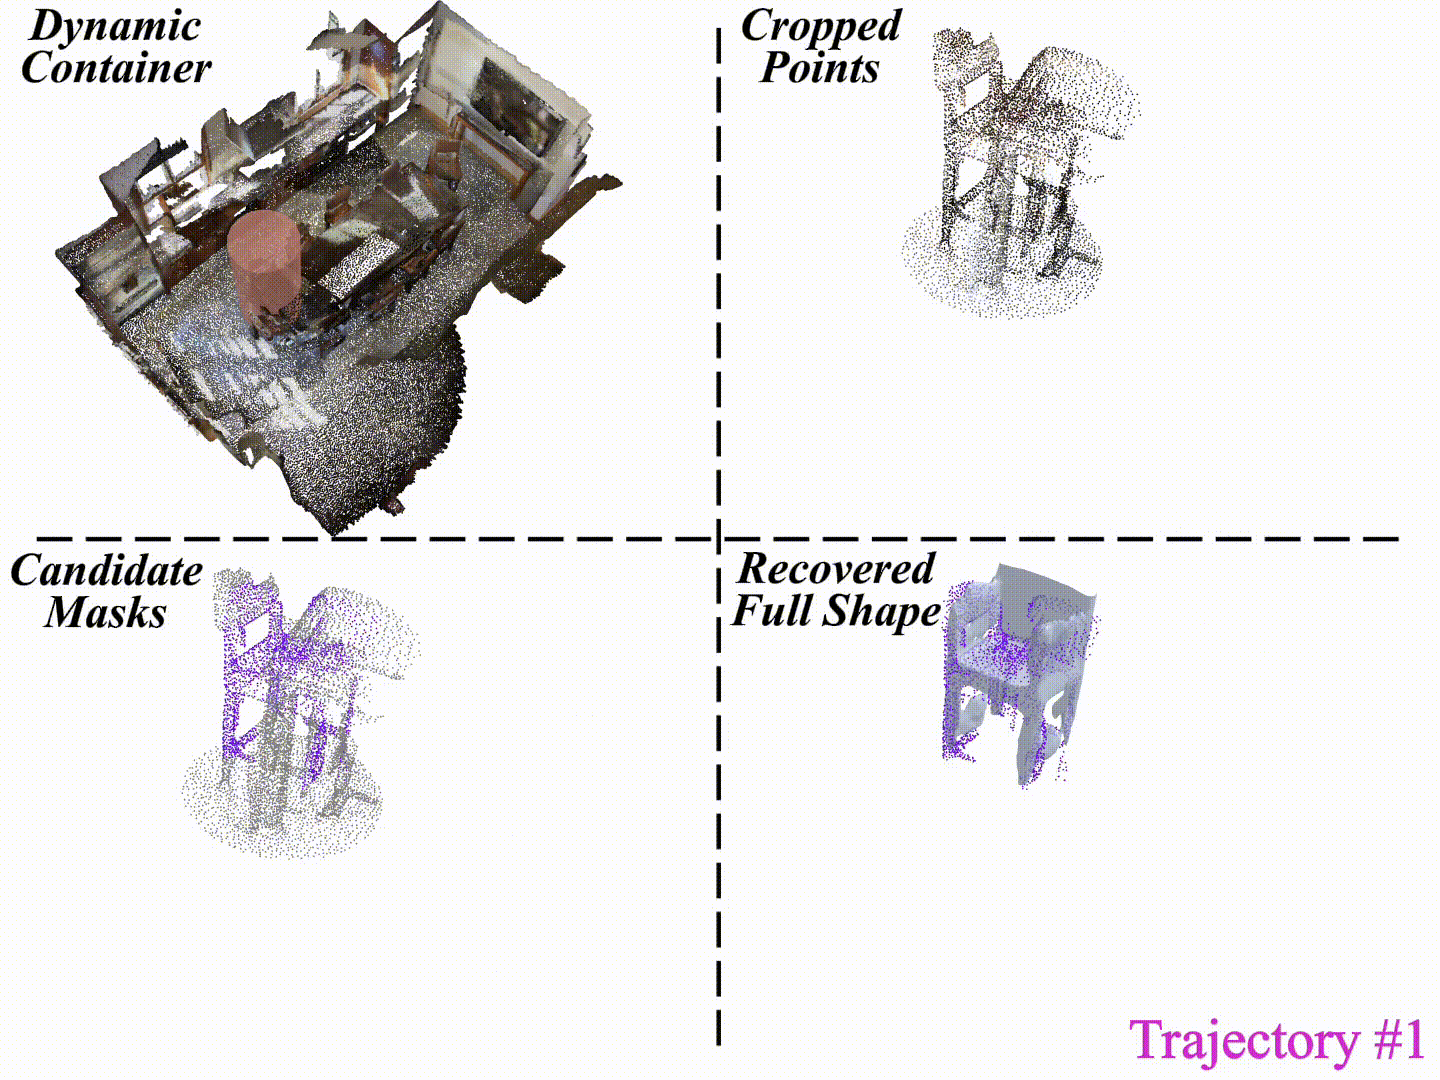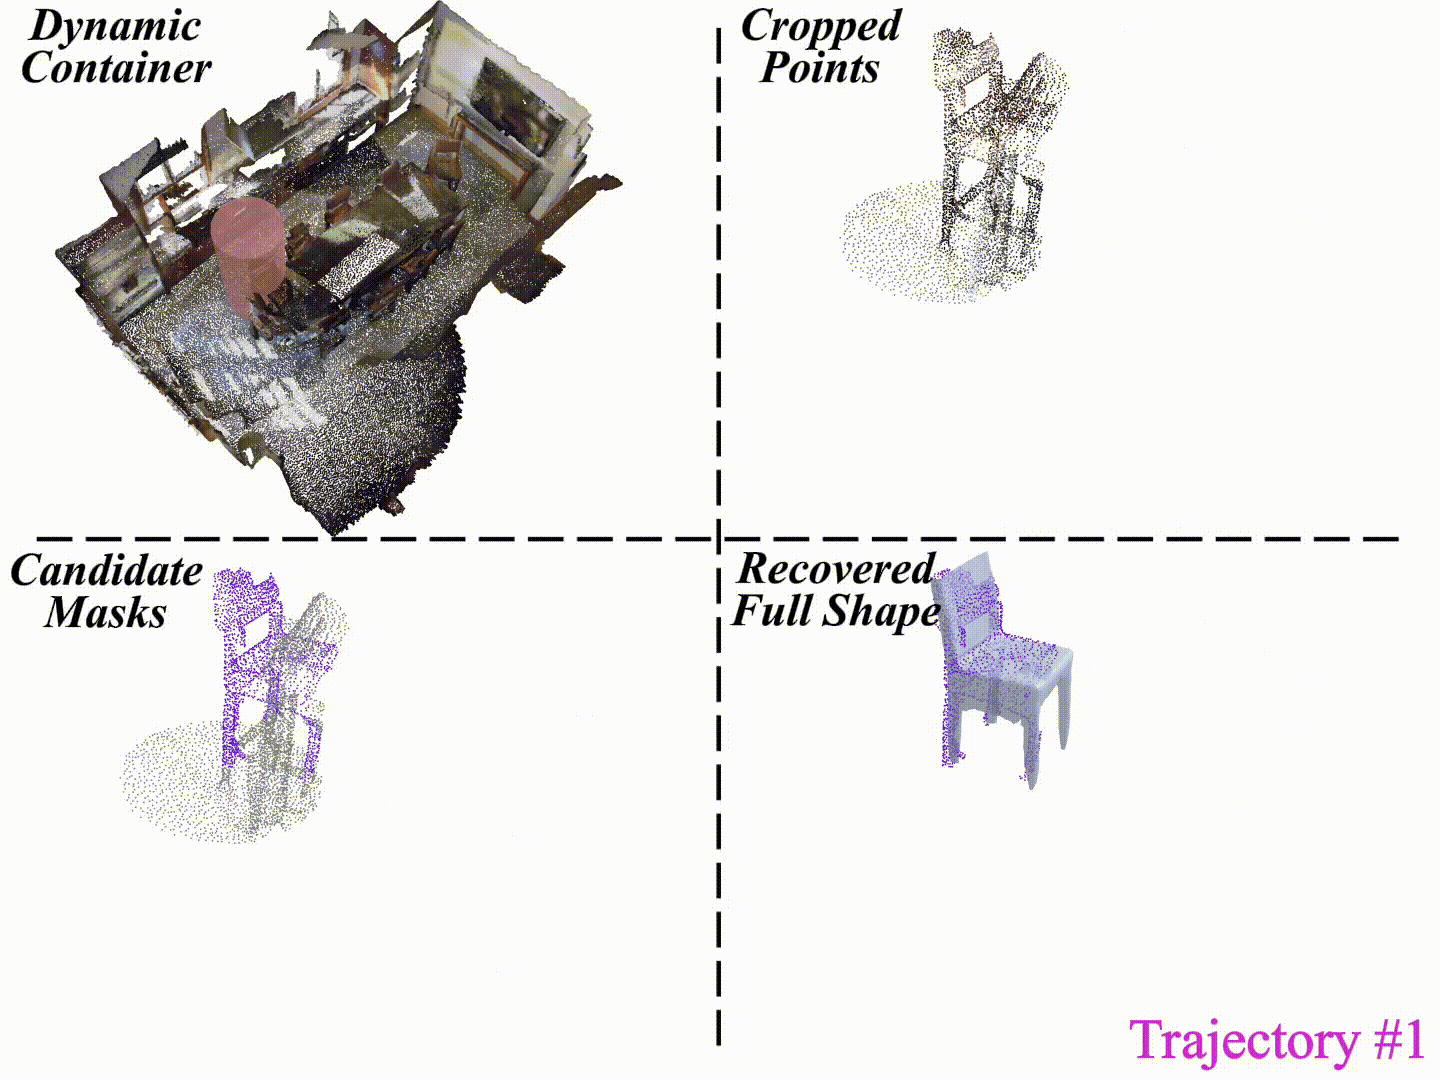
GrabS: Generative Embodied Agent for 3D Object Segmentation without Scene Supervision
@inproceedings{zhang2025grabs,title={{GrabS}: Generative Embodied Agent for 3D Object Segmentation without Scene Supervision},author={Zhang, Zihui and Yang, Yafei and Wen, Hongtao and Yang, Bo},booktitle={The Thirteenth International Conference on Learning Representations},year={2025},note={Spotlight},}
2022
TransGrasp: Grasp pose estimation of a category of objects by transferring grasps from only one labeled instance
@inproceedings{wen2022transgrasp,title={TransGrasp: Grasp pose estimation of a category of objects by transferring grasps from only one labeled instance},author={Wen, Hongtao and Yan, Jianhang and Peng, Wanli and Sun, Yi},booktitle={European Conference on Computer Vision},pages={445--461},year={2022},organization={Springer},}
Self-supervised category-level 6D object pose estimation with deep implicit shape representation
@inproceedings{peng2022self,title={Self-supervised category-level 6D object pose estimation with deep implicit shape representation},author={Peng, Wanli and Yan, Jianhang and Wen, Hongtao and Sun, Yi},booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},volume={36},number={2},pages={2082--2090},year={2022},}